Overview
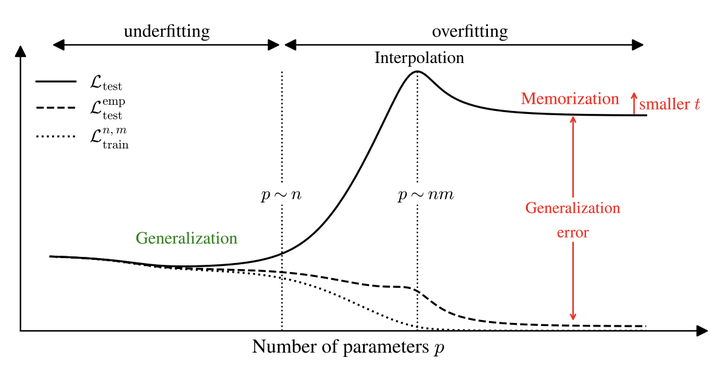
Overparameterization can improve generalization in regression, yet unregularized diffusion models can instead memorize their training set. Combining a solvable random-features model with U-Net experiments, we show that overfitting begins when model size reaches the number of training samples, well before the interpolation peak set by repeated noising. A bias-variance analysis explains why learning the empirical score leads to memorization. Regularization or early stopping allows larger models to outperform unregularized ones.
Type
Publication
arXiv:2609.26392